Last Updated on 09/11/2026 by Eran Feit
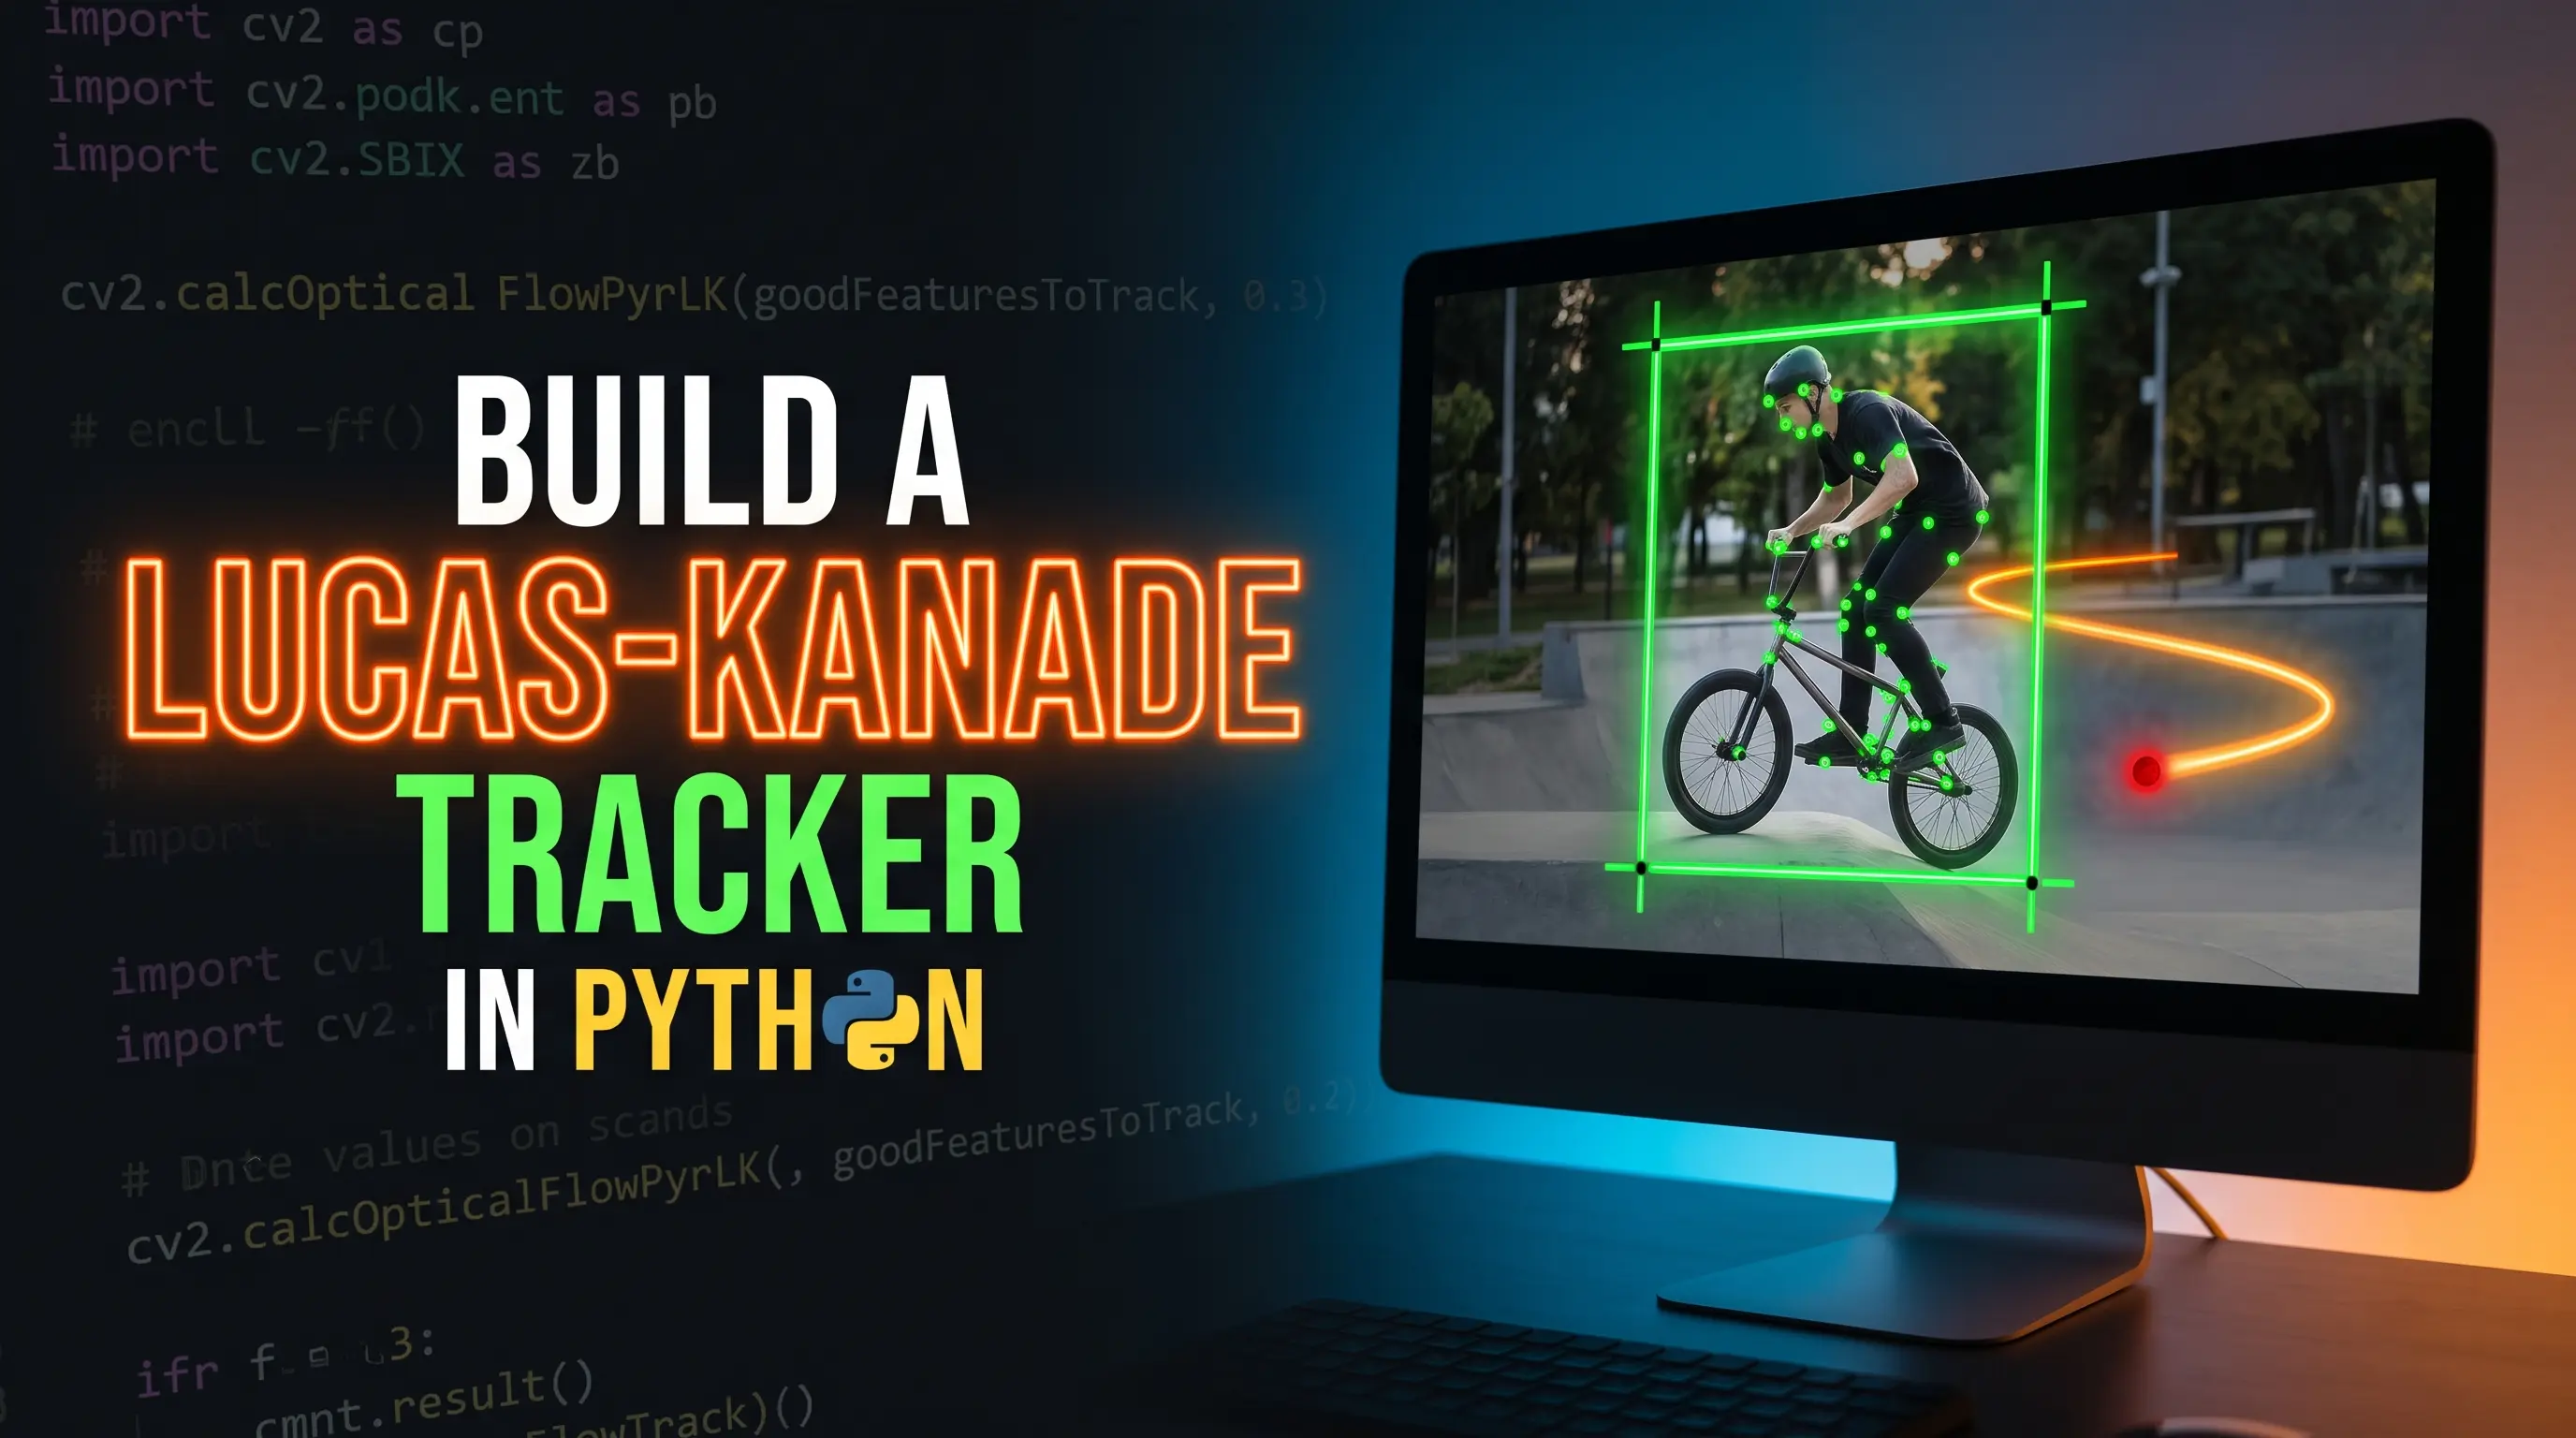
Mastering lucas kanade optical flow opencv implementations allows developers to bridge the gap between static image processing and dynamic video motion analysis. This article breaks down how to construct a robust, lightweight real-time object tracking system in Python without relying on heavy deep-learning frameworks. Instead of processing full-frame calculations that drain compute resources, you will explore how sparse optical flow tracks distinct visual landmarks across consecutive video frames with minimal latency.
Computer vision projects frequently struggle with tracking drift, unpredictable target initialization, and noisy raw trajectories. Rather than leaving you with isolated snippets or theoretical equations, this guide equips you with a production-ready tracking pipeline that stabilizes visual tracking through mathematical filtering. Understanding this foundational technique gives you direct control over video analytics, surveillance feeds, and motion tracking applications where speed and resource efficiency are non-negotiable.
You will achieve this through a complete, hands-on walkthrough built around real-world Python code. The pipeline begins with interactive mouse-drag Region of Interest (ROI) selection using OpenCV primitives, letting you isolate targets dynamically on the fly. From there, the article explains how to seed Shi-Tomasi corner points strictly within that bounded zone, execute pyramidal Lucas-Kanade differential motion tracking, and map the target’s trajectory using exponential moving average smoothing paired with a decaying visual canvas.
By examining both the underlying principles and the line-by-line script architecture, you will gain an end-to-end understanding of sparse motion estimation. Each functional stage—from downscaling video inputs for throughput gains to handling feature drop-off across continuous frames—is dissected to show exactly how mathematical assumptions translate into reliable software execution.
How Lucas-Kanade Optical Flow in OpenCV Actually Tracks Motion The primary goal of optical flow estimation is to quantify the apparent motion of visual patterns between two sequential video frames. In dynamic scenes, objects move, camera perspectives shift, and surface pixels redistribute across coordinate space. Optical flow treats these frame-to-frame shifts as a vector field, assigning velocity and direction vectors to individual points. In computer vision tasks where running high-parameter neural networks creates processing bottlenecks, optical flow provides a fast, mathematically grounded alternative for extracting kinetic information straight from raw pixel intensities.
At the core of the Lucas-Kanade technique are three fundamental assumptions: brightness constancy, temporal persistence, and spatial coherence. Brightness constancy assumes that a point on an object does not change its grayscale intensity simply because it moves from one frame to the next. Temporal persistence implies that the video frame rate is high enough relative to object speed that displacements between steps remain small. Finally, spatial coherence dictates that adjacent pixels belonging to the same surface share identical motion vectors. Because single pixels suffer from the aperture problem—where motion along edges remains ambiguous—Lucas-Kanade groups local neighborhood windows into solvable systems of differential equations solved via least-squares estimation.
OpenCV builds on this classical foundation through a pyramidal architecture, commonly invoked via its pyramidal optical flow implementation. In practical video scenarios, objects frequently move faster than the differential assumption tolerates, causing standard single-scale solvers to lose track. To overcome this limitation, the algorithm constructs an image pyramid where each level downsamples the original resolution. Motion estimation begins at the coarsest, low-resolution level where large pixel jumps appear small, computes an initial motion estimate, and progressively refines that displacement vector down to the original full-resolution frame. This coarse-to-fine refinement makes sparse point tracking exceptionally durable across varying velocities while maintaining ultra-low computational overhead.
Lucas Kanade Optical Flow Result : OpenCV Object Tracking in Python: Lucas Kanade Optical Flow 11 OpenCV Object Tracking in Python: Lucas Kanade Optical Flow 12 Lucas-Kanade vs. Other Motion Tracking Methods: Which One Should You Choose? Motion Tracking Approach Category / Paradigm Computational Overhead Resilience to Illumination & Occlusion Handling of Large / Fast Motion Best Use Case / Ideal Scenario Lucas-Kanade (LK) Sparse Optical Flow Ultra-Low (Runs effortlessly on low-power CPUs & embedded edge devices)Low (Relies strictly on brightness constancy; vulnerable to heavy occlusions)Moderate (Requires multi-scale image pyramids to track larger displacements)High-FPS point tracking, trajectory tracing, stabilization, low-power robotics. Farnebäck / Horn-Schunck Dense Optical Flow High (Calculates motion vectors for every single pixel in the frame)Low to Moderate (Sensitive to global illumination shifts across surfaces)Moderate (Effective for continuous field shifts, but fails on rapid non-rigid jumps)Background motion estimation, camera ego-motion, full-scene dynamic segmentation. KCF / CSR-DCF Correlation Filters (DCF) Low to Medium (Fast Fourier Transform acceleration on standard CPUs)Moderate (Maintains an evolving appearance model; recovers from partial occlusion)High (Tracks bounding box position across larger spatial jumps within search radius)Single-object bounding-box tracking where target scales and rotates moderately. Deep Learning (e.g., SiamRPN++, ByteTrack, RAFT) Neural Networks (Transformers / CNNs) Very High (Demands dedicated GPU hardware or specialized neural accelerators)Very High (Learns semantic invariant features; resilient to shadows, blur, and occlusions)Very High (Handles dramatic scene cuts, fast acceleration, and complex re-identification)Multi-target tracking (surveillance, autonomous driving) where accuracy outweighs hardware constraints.
When evaluating motion tracking architectures, selecting the right approach involves balancing computational efficiency, feature density, and resilience to environmental shifts. The Lucas-Kanade (LK) algorithm represents the pinnacle of classical sparse optical flow , designed specifically to track high-contrast feature points with microsecond latency. Because it solves a localized differential equation via least-squares estimation, LK requires negligible memory and CPU overhead compared to other paradigms. However, this speed comes with strict mathematical assumptions: brightness constancy, small pixel displacements, and spatial coherence. When tracking targets that undergo sudden acceleration, severe occlusion, or dramatic illumination changes, standard LK pipelines can lose tracked features, requiring re-initialization or pyramid scaling to survive larger displacements.
In contrast, dense optical flow algorithms , such as the Gunnar Farnebäck method or Horn-Schunck, compute motion vectors for every single pixel across the entire image frame rather than a sparse subset of corners. While dense estimation yields a complete, continuous motion field—invaluable for camera stabilization, scene segmentation, and ego-motion estimation—it demands significantly higher computational throughput. In real-time video tracking scenarios where the objective is following a discrete entity (such as a vehicle, athlete, or selected object), processing millions of irrelevant background vectors introduces substantial compute latency without offering additional tracking fidelity over a well-initialized sparse LK system.
Moving beyond classical optical flow, correlation-filter and appearance-based trackers —including Kernelized Correlation Filters (KCF), Discriminative Correlation Filters with Channel and Spatial Reliability (CSR-DCF), and MeanShift/CamShift—approach the tracking task from an object-centric boundary perspective rather than raw pixel differential vectors. KCF and CSR-DCF train an adaptive regressor in the frequency domain using circular shifts, allowing them to track an entire bounding box while automatically updating an internal representation of the target’s appearance. These trackers handle scale variation, rotation, and slight deformations far better than pure Lucas-Kanade, though they lack LK’s sub-pixel spatial accuracy and can succumb to background clutter if the target blends into its surroundings.
At the modern high-end spectrum sit deep learning-based motion tracking models , ranging from Transformer-driven single-object trackers (such as OSTrack and SiamRPN++) to multi-object tracking architectures (like ByteTrack, BoT-SORT, or deep optical flow models like RAFT). Deep models extract rich semantic features that make them extraordinarily resilient to extreme occlusion, motion blur, and dramatic perspective distortions that cause classical mathematical assumptions to collapse. Nevertheless, deep networks require dedicated GPU acceleration, introduce significant inference latency, and function as opaque models that require vast labeled training datasets.
For real-time embedded devices, high-frame-rate edge applications, and resource-constrained environments where sub-pixel geometric tracking is paramount, Lucas-Kanade remains the benchmark choice for raw execution speed and deterministic mathematical control.
OpenCV Object Tracking in Python: Lucas Kanade Optical Flow 13 Building an Interactive Lucas-Kanade Motion Tracker in Python What Makes This Tracking Pipeline Different from Standard Examples? Most optical flow tutorials hardcode point coordinates or track every moving pixel across an unconstrained frame, leading to visual clutter and rapid drift. This implementation gives you complete operational control: you interactively designate the exact target with your mouse, seed corner detectors strictly within that bounding box, filter tracking noise using exponential smoothing, and render an auto-fading trajectory canvas that visually charts the target’s true path through space.
The primary objective of this code is to establish a deterministic, lightweight motion tracking pipeline that runs at full frame rates without deep learning dependencies. Video streams introduce significant variability—varying lighting, fast motion, and camera jitter—which quickly degrade standard differential trackers. By restricting computational attention to a user-defined sub-region and pairing pyramidal optical flow with temporal smoothing, this script demonstrates how to reliably isolate, follow, and visualize an object’s trajectory across complex video footage.
Execution begins with smart stream initialization and user-driven target acquisition. The script loads the raw video, downscales incoming frames by 50% to slash mathematical overhead, and spawns an interactive OpenCV selection window. Instead of guessing where the target sits, you simply drag a bounding box around the subject using your mouse. This user-defined region immediately acts as an isolated binary mask, ensuring that subsequent corner detection algorithms ignore irrelevant background noise and evaluate only the pixels belonging to the target of interest.
Once the target area is bounded, the pipeline initializes Shi-Tomasi feature tracking using optimal corner detection heuristics. The algorithm locates the most salient, high-contrast visual anchors within the masked zone, preparing a compact matrix of tracking coordinates. From there, the pyramidal Lucas-Kanade solver takes over frame by frame, projecting these discrete points forward in time across multi-scale image pyramids. This tiered spatial approach allows the system to absorb larger displacements—such as a speeding bicycle or a sprinting athlete—that would otherwise break basic differential flow assumptions.
The final phase transforms raw point tracking into a clean, intuitive motion visualization. Instead of letting individual feature jitter degrade the output, the code computes the median position across all actively tracked points and applies exponential moving average smoothing to stabilize the target’s estimated center. Simultaneously, a secondary graphical canvas registers each step of the path and applies a geometric decay multiplier to older coordinates. This architecture produces a smooth, fading orange trajectory line overlaid seamlessly onto the live video feed, delivering a production-grade tracking visual that is written directly to an exportable video file.
Link to the tutorial here
Download the code for the tutorial here or here
Link for Medium users here
Master Computer Vision
Follow my latest tutorials and AI insights on my
Personal Blog .
Beginner Complete CV Bootcamp
Foundation via PyTorch & TF.
Get Started → Interactive Deep Learning with PyTorch
Hands-on interactive practice.
Start Learning → Advanced Modern CV: GPT & OpenCV4
Vision GPT production models.
Go Advanced → OpenCV Object Tracking in Python: Lucas Kanade Optical Flow 14 Setting Up Video Capture and Initializing the Output Stream Handling raw video inputs requires deliberate pipeline setup to ensure consistent real-time execution speeds. High-resolution video feeds demand massive floating-point matrix operations that choke real-time trackers if left at native dimensions. In this foundational step, we ingest the target media, verify stream integrity, and immediately downscale each frame to strike an ideal balance between optical flow fidelity and compute throughput.
Preparing the output stream is equally vital when authoring modular computer vision scripts. Rather than relying on volatile screen recordings, OpenCV lets you bind a hardware-accelerated video writer instance directly to the dimensions and framerate of your downsampled canvas. This defensive programming approach prevents stream desynchronization and writes every processed pixel accurately to disk.
By mastering stream allocation and initial geometry scaling early, you establish an optimized processing loop for lucas kanade optical flow opencv workflows. Every downstream tracking step—from corner detection to trajectory interpolation—inherits this clean, predictable coordinate grid without burning unnecessary CPU cycles.
How Does Downscaling the Input Frame Improve Tracking Performance? Downscaling the input frame cuts total pixel volume by three-quarters, slashing the mathematical burden of neighborhood differential convolutions and boosting optical flow frame rates without compromising point tracking accuracy.
### Install required packages for video processing and numerical computation # pip install opencv-python numpy ### Import the core OpenCV library for computer vision operations import cv2 ### Import NumPy for efficient array manipulation and matrix calculations import numpy as np ### Define the relative path to the input video file test_video_path = " Best-Object-Detection-models/Object-Tracking using Lucas-Kanade Optical Flow/A BMX biker.mp4 " ### Initialize the video capture object with the specified file cap = cv2.VideoCapture ( test_video_path ) ### Read the very first frame to confirm stream access and get dimensions ret, first_frame = cap.read () ### Verify whether the video frame was successfully decoded if not ret: print ( "Error: Could not read the video file." ) exit () ### Downscale the initial frame by 50 percent to accelerate subsequent processing first_frame = cv2.resize ( first_frame, (0, 0 ) , fx=0.5, fy=0.5) ### Define the output destination path for the processed video file output_video_path = " Best-Object-Detection-models/Object-Tracking using Lucas-Kanade Optical Flow/output_tracked_trajectory.mp4 " ### Query the input video metadata to extract its native playback frame rate fps = cap.get ( cv2.CAP_PROP_FPS ) ### Validate that the FPS metadata exists or fallback to a standard 30 frames per second if fps == 0 or np.isnan ( fps ) : fps = 30.0 # Fallback FPS if video metadata is missing ### Extract the height and width from the resized first frame shape h_out, w_out = first_frame.shape[:2] ### Define the MP4V video codec specification for encoding the output file fourcc = cv2.VideoWriter_fourcc ( * " mp4v " ) ### Initialize the VideoWriter object with destination path, codec, fps, and frame size out = cv2.VideoWriter ( output_video_path, fourcc, fps, (w_out, h_out ) ) This setup phase prepares our video stream, establishes safe frame dimensions, and configures the video writer to ensure our tracked output is saved smoothly without runtime errors.
Interactive Target Selection and Feature Extraction Automated object trackers often struggle when initialized in cluttered environments where backgrounds compete with the target. Instead of hardcoding bounding coordinates, this stage introduces a mouse-driven Region of Interest (ROI) workflow. By giving the user direct spatial control over target isolation, we eliminate edge clutter and focus tracking attention squarely on the subject.
Once you highlight the subject, the script transforms that bounding rectangle into an isolated binary mask. This mask confines feature extraction strictly to the target’s physical geometry. Pixels outside the boundary are completely ignored, preventing the tracker from latching onto stationary background elements or irrelevant high-contrast artifacts.
Within this isolated mask, we execute the Shi-Tomasi corner detection algorithm using cv2.goodFeaturesToTrack. Unlike standard Harris corners, Shi-Tomasi identifies optimal eigenvalue intersections that resist deformation. These high-salience points serve as the resilient visual anchors that our lucas kanade optical flow opencv pipeline tracks across successive video frames.
Why Do We Restrict Shi-Tomasi Feature Detection with a Binary Mask? Using a binary mask guarantees that feature detection isolates high-contrast corners exclusively within the user’s selected ROI, preventing the algorithm from locking onto stationary background textures.
### Open an interactive window allowing the user to drag a bounding box around the target roi = cv2.selectROI ( "Select Target" , first_frame, fromCenter=False, showCrosshair=True ) ### Destroy the selection window immediately after the user confirms their selection cv2.destroyWindow( "Select Target" ) ### Unpack the bounding box coordinates into origin and dimension variables x, y, w, h = roi ### Print the selected ROI coordinates to the console for verification print (f "Selected ROI: x={x}, y={y}, w={w}, h={h}" ) ### Validate whether a valid region was highlighted by the user if w == 0 or h == 0 : print ( "Error: No ROI selected." ) out.release () cap.release () exit () ### Convert the initial colored frame to grayscale for intensity-based gradient calculations prev_gray = cv2.cvtColor ( first_frame, cv2.COLOR_BGR2GRAY ) ### Allocate a blank single-channel black mask matching the frame dimensions mask = np.zeros_like ( prev_gray ) ### Paint the rectangular area of the selected ROI white to isolate feature detection mask[y:y + h, x:x + w] = 255 # Create a mask for the ROI ### Detect the strongest Shi-Tomasi corner features specifically within the white mask zone p0 = cv2.goodFeaturesToTrack ( prev_gray, mask=mask, maxCorners= 25 , qualityLevel= 0.1 , minDistance= 7 ) By isolating the target with a binary mask and extracting Shi-Tomasi corner points, we ensure the tracking engine follows only the intended subject rather than random background textures.
Tracking Features with Pyramidal Optical Flow and Smoothing Real-world video motion rarely moves at a gentle, uniform crawl. Fast-moving subjects like athletes or vehicles quickly break standard differential tracking assumptions because their frame-to-frame pixel displacements exceed localized search windows. To conquer this challenge, our pipeline leverages pyramidal Lucas-Kanade tracking (cv2.calcOpticalFlowPyrLK), resolving motion down from coarse, low-resolution pyramid levels to sub-pixel coordinates.
Tracking multiple independent points introduces spatial noise and occasional tracking loss. To eliminate erratic jumps, our code applies a two-tier filtering strategy: it extracts the statistical median across all surviving feature points, then applies an Exponential Moving Average (EMA). This dynamic smoothing filter dampens high-frequency jitter while preserving true motion direction.
The continuous loop updates feature matrices dynamically. As the subject maneuvers across the frame, successfully tracked points from the current frame immediately become the starting coordinates for the next iteration. This ensures the lucas kanade optical flow opencv pipeline maintains uninterrupted tracking across continuous video streams.
How Does Pyramidal Tracking Prevent Feature Loss During Rapid Motion? Pyramidal tracking builds multi-scale image representations where large frame-to-frame displacements appear as small, manageable shifts at coarser levels, allowing the algorithm to maintain tracking lock during sudden accelerations.
### Configure hyperparameter dictionary for the iterative Lucas-Kanade tracking algorithm lk_params = dict ( winSize = ( 19 , 19 ) , maxLevel = 3 , criteria = ( cv2.TERM_CRITERIA_EPS | cv2.TERM_CRITERIA_COUNT, 20 , 0.03 ) , ) ### Initialize a dynamic list structure to store consecutive smoothed path coordinates trajectory_points = [] # List to store trajectory points ### Create an empty black graphical canvas identical in shape to the resized frame for drawing trail_canvas = np.zeros_like ( first_frame ) # Canvas to draw the trajectory ### Initialize the persistent variable that holds the exponentially smoothed center position smoothed_center = None # Initialize smoothed center point ### Define the exponential smoothing factor weighting new coordinates against historical position alpha = 0.35 # Smoothing factor for exponential moving average ### Execute the primary continuous processing loop while the video capture stream remains open while cap.isOpened () : ### Read the subsequent consecutive frame from the input stream ret, frame = cap.read () ### Terminate execution loop cleanly if the video ends or frame reading fails if not ret: break ### Downscale the current frame by 50 percent to align with initialized coordinate dimensions frame = cv2.resize ( frame, (0, 0 ) , fx= 0.5 , fy= 0.5 ) ### Convert the incoming RGB image to a single-channel grayscale intensity matrix frame_gray = cv2.cvtColor ( frame, cv2.COLOR_BGR2GRAY ) ### Calculate sparse optical flow between previous and current frames using pyramids p1, st, _ = cv2.calcOpticalFlowPyrLK ( prev_gray, frame_gray, p0, None, ** lk_params ) ### Confirm that valid tracking coordinates and status vectors were returned by the solver if p1 is not None and st is not None: ### Filter and retain exclusively those feature points that were successfully tracked good_points = p1[st == 1 ] ### Ensure at least one valid tracked feature point survived the differential calculation if len(good_points ) > 0: ### Calculate the robust median horizontal coordinate across all tracked points raw_x = np.median ( good_points[:, 0 ] ) ### Calculate the robust median vertical coordinate across all tracked points raw_y = np.median ( good_points[:, 1 ] ) ### Initialize smoothed center directly with raw median values on the first valid iteration if smoothed_center is None: smoothed_center = (raw_x, raw_y ) ### Blend previous smoothed position with incoming raw detection using exponential smoothing else: sx = alpha * raw_x + (1 - alpha ) * smoothed_center [ 0 ] sy = alpha * raw_y + (1 - alpha ) * smoothed_center [ 1 ] smoothed_center = (sx, sy ) ### Append current smoothed position as an integer tuple into the trajectory history trajectory_points.append((int(smoothed_center[0] ), int ( smoothed_center[1] ) )) ### Prune the path history array to maintain a maximum window of 35 coordinate steps if len(trajectory_points ) > 35: trajectory_points.pop(0 ) ### Render green circles over each individual feature point actively tracked for pt in good_points: px, py = pt.ravel () cv2.circle(frame, (int(px), int ( py ) ), 3, ( 0, 255 , 0 ) , -1) ### Render a prominent red marker identifying the smoothed central anchor of the target cv2.circle(frame, (int(smoothed_center[0]), int ( smoothed_center[1] ) ), 6, ( 0, 0 , 255 ) , -1) ### Reshape current surviving points to serve as the reference coordinates for next frame p0 = good_points.reshape ( -1, 1 , 2 ) By combining multi-scale pyramidal tracking with median calculation and exponential smoothing, our pipeline follows rapid motion stably without suffering from high-frequency coordinate jitter.
Rendering the Fading Trajectory Trail and Final Video Export Raw coordinates provide little value if the final visualization looks cluttered and messy. Drawing static, permanent lines across an entire video sequence quickly turns your preview window into an unreadable tangle of overlapping lines. To create an intuitive, professional display, our pipeline renders a dynamic fading trail that emphasizes the target’s recent trajectory while naturally dissolving older positions.
We accomplish this using a dedicated graphical canvas and OpenCV’s cv2.multiply function. In each frame iteration, we multiply the canvas pixel values by an attenuation coefficient (0.92). This gradually dims older line segments toward black without complex array slicing. We then draw the latest trajectory segment in bright orange and combine the trail canvas with the current video frame using saturated pixel addition (cv2.add).
The composited frame is displayed live and written directly to disk via our configured VideoWriter. Once the user presses the exit key or the stream finishes, all windows close cleanly and memory buffers are flushed. This completes our end-to-end lucas kanade optical flow opencv pipeline, producing a polished, shareable motion tracking video.
How Does the Decay Multiplier Create a Fading Trajectory Trail? Multiplying the canvas pixel intensities by a decay factor (0.92) each frame gradually dims earlier drawn lines toward zero, producing a smooth fading motion trail without manually clearing coordinate arrays.
### Attenuate the trail canvas pixel intensities by 8 percent to create a progressive fading trail trail_canvas = cv2.multiply ( trail_canvas, 0.92 ) # Fade the trail ### Render connected line segments if at least two historical trajectory coordinates exist if len(trajectory_points ) > = 2: for i in range ( 1, len ( trajectory_points )) : cv2.line(trail_canvas, trajectory_points[i - 1 ], trajectory_points[i], (0, 165 , 255 ), 3) # Draw the trajectory line (orange) ### Merge the fading trajectory canvas cleanly over the active video frame using saturated addition output_frame = cv2.add ( frame, trail_canvas ) ### Encode and write the composited visualization frame to the disk output video file out.write(output_frame ) ### Render the final composited frame in an interactive OpenCV desktop preview window cv2.imshow( "Optical flow tracking" , output_frame ) ### Cache the current grayscale image to serve as the reference frame for the next iteration prev_gray = frame_gray.copy () # Update previous frame for the next iteration ### Intercept keyboard input to break the loop if the user presses 'q' or the 'Esc' key if cv2.waitKey(15 ) & 0xFF in [ord( ' q ' ), 27]: # Press 'q' or 'Esc' to exit break ### Release the input video capture stream resource from system memory cap.release () ### Finalize and close the video output encoding buffer on disk out.release () ### Destroy and dismiss all active OpenCV graphical user interface windows cv2.destroyAllWindows () ### Print confirmation statement verifying that the tracked output video file was successfully generated print ( f "Video saved successfully to: {output_video_path}" ) This final stage blends the fading motion trail into the video frame, displays the live result, and saves the completed tracking visualization cleanly to disk.
Frequently Asked Questions What is the main difference between Lucas-Kanade and Farnebäck optical flow? Lucas-Kanade is a sparse optical flow method that tracks a select set of high-contrast feature points with minimal latency. In contrast, Farnebäck is a dense method that calculates motion vectors for every pixel in the frame, requiring substantially more computational power.
Why does Lucas-Kanade tracking fail when an object moves very quickly? The standard Lucas-Kanade algorithm relies on a small-displacement differential assumption. If an object moves farther between frames than the neighborhood window size can accommodate, the solver fails to match features unless multi-level image pyramids are used.
What role does cv2.selectROI play in this workflow? The cv2.selectROI function allows users to interactively drag a bounding box around their target with the mouse. This isolates the tracking region so that corner detection evaluates only the target, ignoring extraneous background points.
Why are Shi-Tomasi corners preferred over Harris corners for tracking? Shi-Tomasi corner detection uses the minimum eigenvalue of the gradient matrix rather than the Harris response score. This modification identifies stronger, more stable corner landmarks that resist geometric distortion during tracking.
What does the maxLevel parameter do in cv2.calcOpticalFlowPyrLK? The maxLevel parameter determines the height of the Gaussian image pyramid. A value of 3 builds three downsampled layers, enabling the algorithm to detect large displacements at lower resolutions before refining them at native resolution.
How does exponential moving average (EMA) smoothing improve trajectory quality? EMA smoothing weights recent median coordinates against historical averages using a smoothing factor (alpha). This eliminates high-frequency jitter caused by momentary point displacement without introducing lag.
Why do we convert video frames to grayscale before calculating optical flow? Optical flow depends on brightness constancy and spatial intensity gradients across axes. Processing single-channel luminance data eliminates redundant color information and significantly speeds up differential calculations.
How does the fading effect on the trajectory line work? The trajectory is drawn onto a dedicated blank canvas that gets multiplied by 0.92 on each frame iteration. This geometric attenuation fades older lines toward black before the canvas is merged with the live frame using cv2.add.
What happens if all tracked feature points leave the frame or get occluded? If all feature points are lost, good_points becomes empty and tracking pauses at the last known position. Production systems typically handle this by re-triggering Shi-Tomasi corner detection within the last estimated bounding area.
Can this optical flow script run on live webcams or RTSP streams? Yes. Replacing the file path in cv2.VideoCapture() with an integer index (such as 0 for an integrated webcam) or an RTSP stream URL runs the exact same tracking pipeline on live camera feeds.
Conclusion Building a production-ready tracking system does not always demand heavy deep-learning neural networks or power-hungry GPUs. As demonstrated throughout this tutorial, classical computer vision algorithms remain extraordinarily effective when paired with smart data filtering and sound engineering choices. By leveraging lucas kanade optical flow opencv in Python, you can achieve sub-pixel spatial tracking accuracy and high frame rates on standard CPU hardware.
The true strength of this pipeline lies in its modular synergy. Interactive mouse-driven target selection eliminates initial background noise; Shi-Tomasi corner detection isolates resilient feature landmarks; multi-scale image pyramids absorb larger motion displacements; and exponential moving average smoothing filters out raw sensor jitter. Finally, rendering the motion path onto a fading trajectory canvas transforms raw coordinate points into an intuitive, polished visual deliverable.
Whether you are developing automated robotics, analyzing athletic biomechanics, or building real-time video analytics software, this lightweight Lucas-Kanade pipeline provides an adaptable, deterministic foundation. Experiment with different pyramid levels, test varying smoothing factors (alpha), and integrate automated feature re-initialization to tailor this motion tracking engine to your specific computer vision projects.
Connect : ☕ Buy me a coffee — https://ko-fi.com/eranfeit
🖥️ Email : feitgemel@gmail.com
🌐 https://eranfeit.net
🤝 Fiverr : https://www.fiverr.com/s/mB3Pbb
Enjoy,
Eran
 Skip to content